|
I'm a CS PhD student at PolyU 🇭🇰 in the Computing department, where I'm supervised by Prof. Ninghao Liu. My research focuses on enhancing the efficiency of training and deploying advanced agentic LLMs while ensuring robustness, generalization performance, and auditable. I received the M.S. degree from the School of Computer and Communication Sciences (IC) at EPFL 🇨🇭 in March 2026, specializing in Natural Language Processing. Previously, I completed my master thesis at NLP Lab, EPFL, supervised by Prof. Antoine Bosselut and Zeming Chen. During my master studies, I was also fortunate to spend time as a research student supervised by Prof. Boi Faltings and Shaobo Cui, research assistant in HKUST(GZ) supervised by Prof. Chengwei Qin, LLM infrastructure developer intern at the ICRC supervised by Prof. Mary-Anne Hartley, and NLP algorithm researcher intern in miHoYo Luming AI group supervised by Yanran Li. I got my bachelor's degree from Xi'an Jiaotong University 🇨🇳. For pronunciation, my full name is /how-tee-en woo/, but just calling me Haotian is a lot easier :) Google Scholar / Email / Twitter / Github |
|
|
[Sep 24, 2026] One work on reasoning consolidation through test-time training was accepted to NeurIPS 2026! See you in Sydney! [Sep 1, 2026] I officially started my PhD at PolyU! [Apr 4, 2026] One paper on enhancing LLM reasoning through interactive learning was accepted to Findings of ACL 2026! [Feb 21, 2026] One paper on data-free model merging was accepted to CVPR 2026! [Jan 3, 2026] One paper on benchmarking error propagation in multi-step reasoning was accepted to EACL 2026! |
|
(* denotes equal contribution) |
|
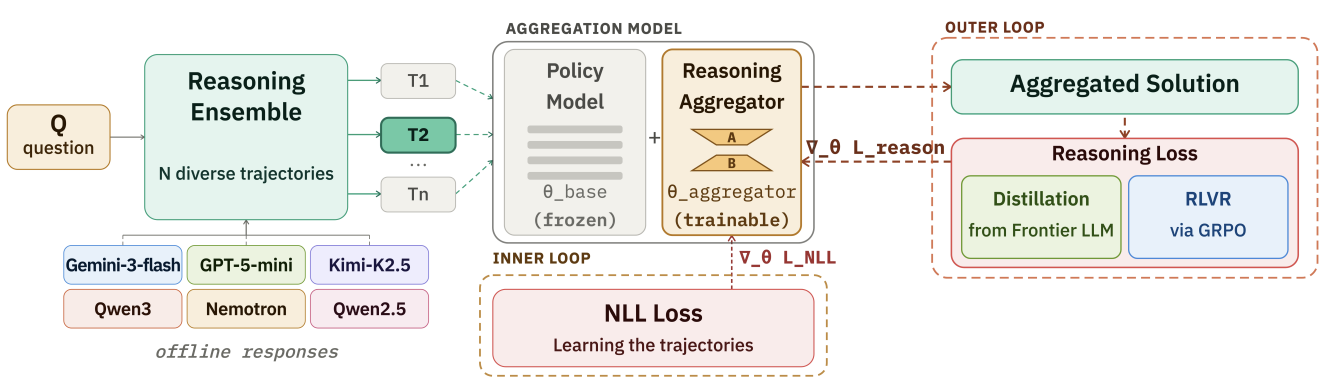
Haotian Wu*, Zeming Chen*, Hao Zhao, Antoine Bosselut NeurIPS 2026 [arXiv coming soon] We introduce CORAL, a test-time learning framework that consolidates parallel reasoning trajectories into a lightweight LoRA-based parametric memory before synthesizing a final answer. CORAL is meta-learned through nested optimization to extract complementary reasoning across trajectories rather than treating each solution independently. We also construct OpenParallelThinking, a corpus of 12,810 math problems with trajectories from six LLMs at varying quality levels. Across challenging mathematics and STEM benchmarks, CORAL outperforms strong aggregation baselines by 20% overall and remains robust even when consolidating entirely incorrect solutions. |
|
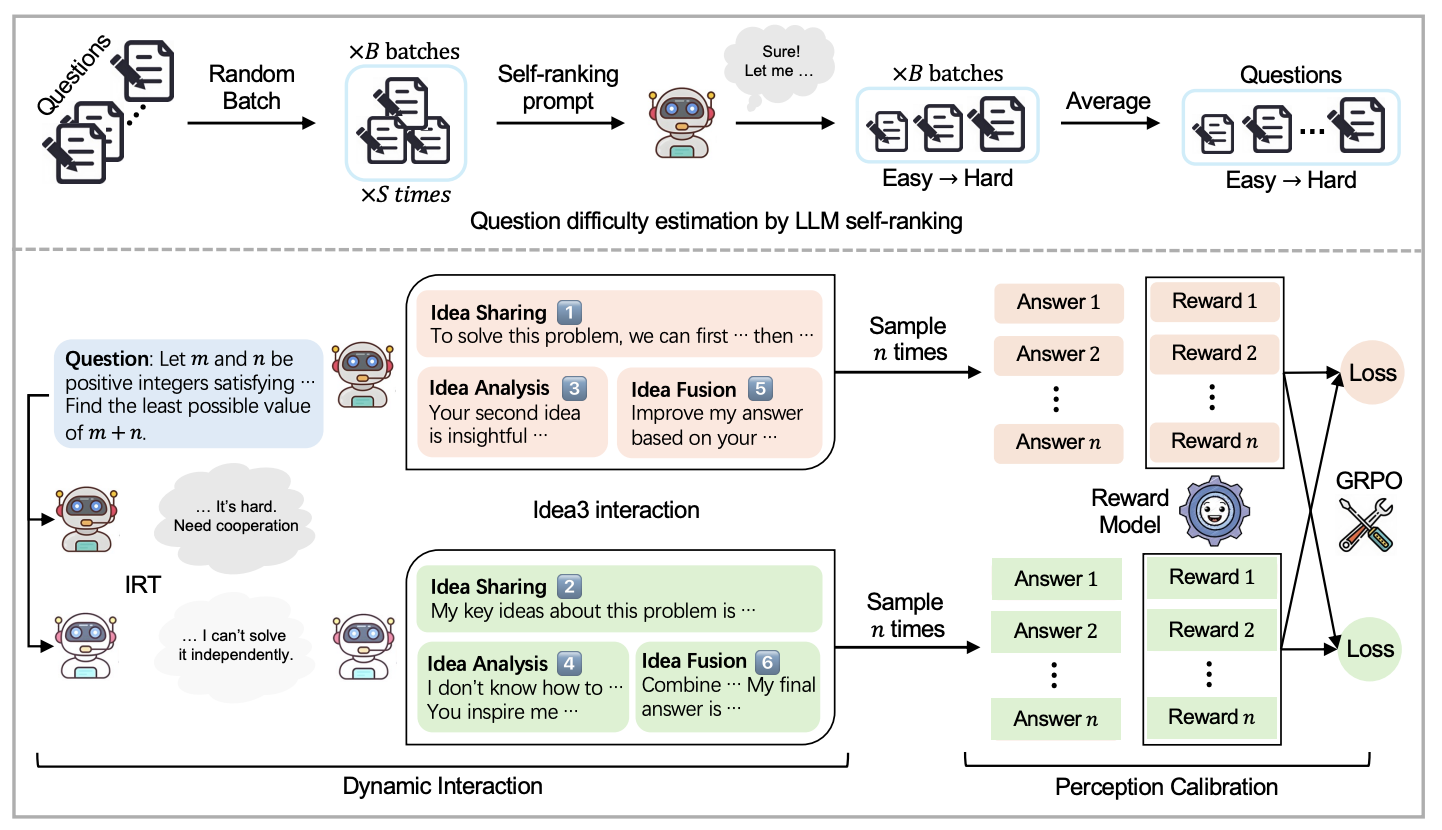
Hehai Lin, Shilei Cao, Sudong Wang, Haotian Wu, Minzhi Li, Linyi Yang, Juepeng Zheng, Chengwei Qin Findings of ACL 2026 [Paper] We propose ILR, a co-learning framework that uses multi-agent interaction to improve each LLM's independent reasoning ability. Dynamic Interaction adaptively chooses cooperative or competitive strategies according to problem difficulty and model capability, while the Idea3 process enables models to share, analyze, and fuse ideas. Perception Calibration then integrates one model's reward characteristics into another through GRPO. Experiments across mathematical and coding benchmarks show that ILR improves reasoning robustness, outperforms fixed interaction strategies, and scales beyond two-model settings. |
|
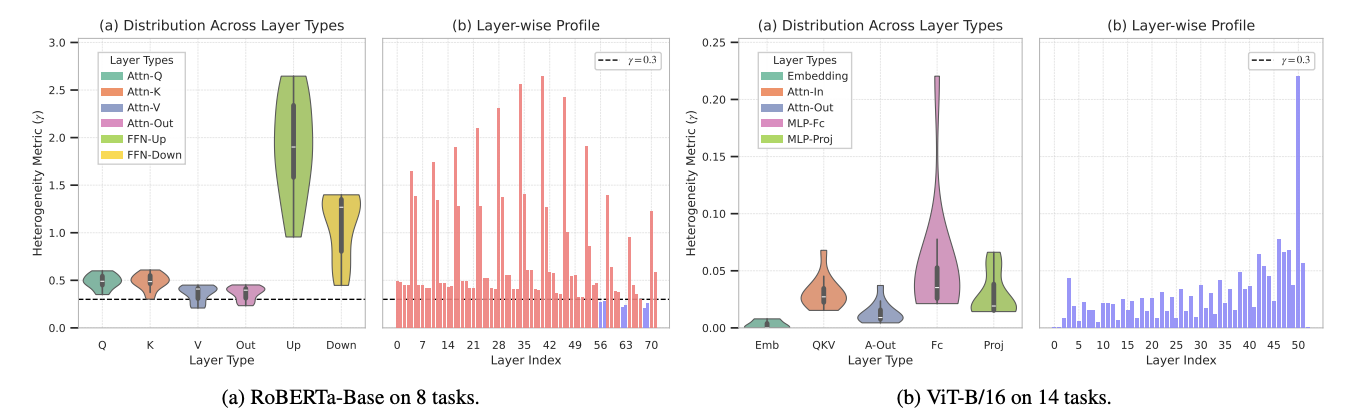
Bo Xu, Haotian Wu, Hehai Lin, Weiquan Huang, Beier Zhu, Yao Shu, Chengwei Qin CVPR 2026 [arXiv] We present ACE-Merging, a data-free model merging framework based on adaptive covariance estimation. Our analysis shows that the task-specific input covariance required for optimal merging can be inferred directly from differences between fine-tuned model parameters, eliminating the need for training data, retraining, or architectural changes. This insight yields an efficient closed-form solution that mitigates interference among task experts. Experiments on vision and language benchmarks establish new state-of-the-art data-free merging performance, including a four-point average improvement over prior methods across seven GPT-2 tasks. |
|
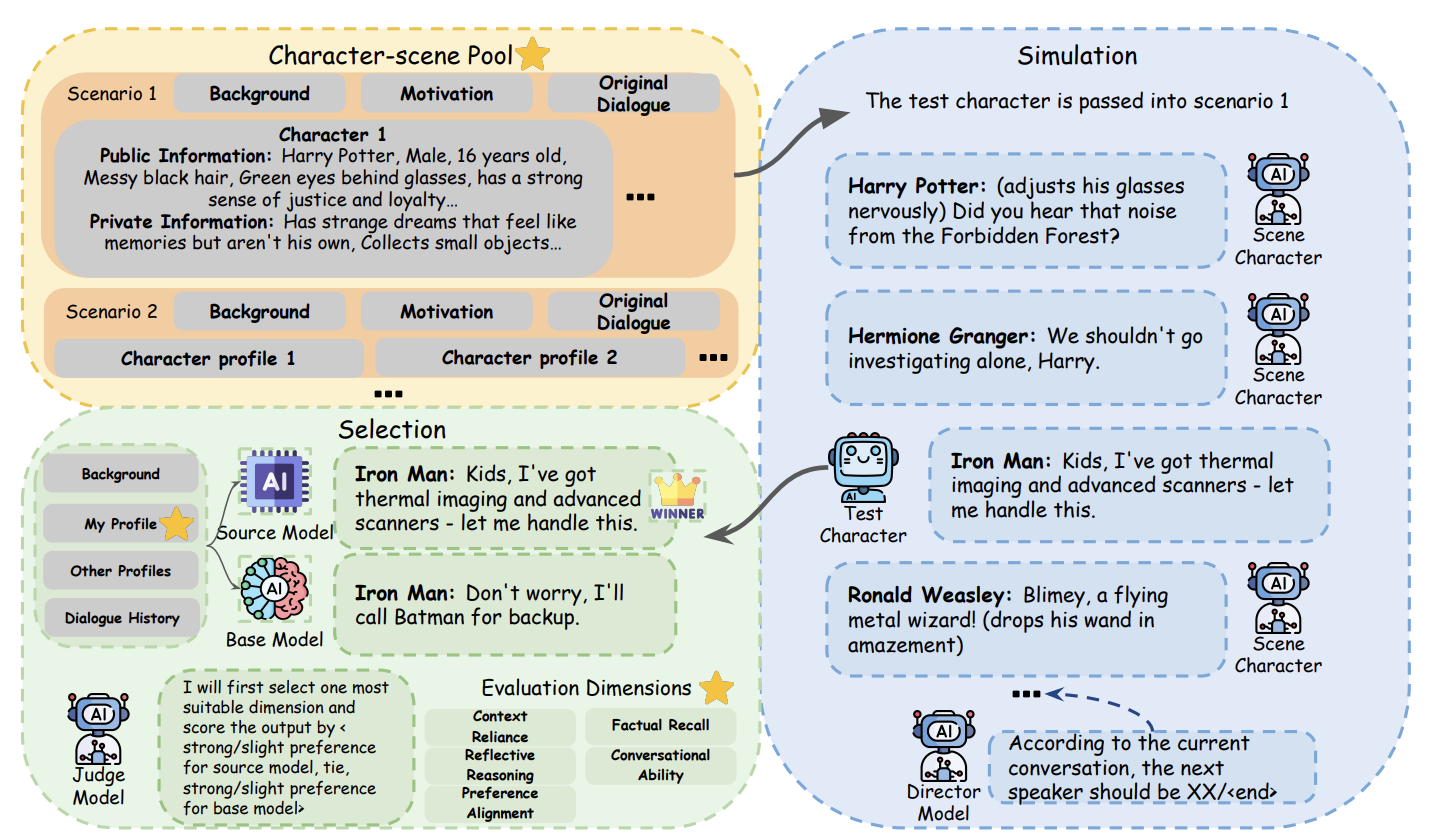
Haotian Wu*, Shufan Jiang*, Chios Chen, Yiyang Feng, Hehai Lin, Heqing Zou, Yao Shu, Chengwei Qin arXiv preprint [arXiv] We introduce FURINA-Builder, a scalable multi-agent pipeline for constructing fully customizable role-playing benchmarks across arbitrary characters, scenarios, and prompt formats. Using this pipeline, we create FURINA-Bench with established and synthesized characters and fine-grained, dimension-specific evaluation criteria. Evaluations of leading LLMs reveal that established characters remain easier than synthesized ones, model scale does not monotonically reduce hallucinations, and stronger reasoning introduces a trade-off: it improves role-playing quality while increasing role-playing hallucinations, forming a broader performance-reliability Pareto frontier. |
|
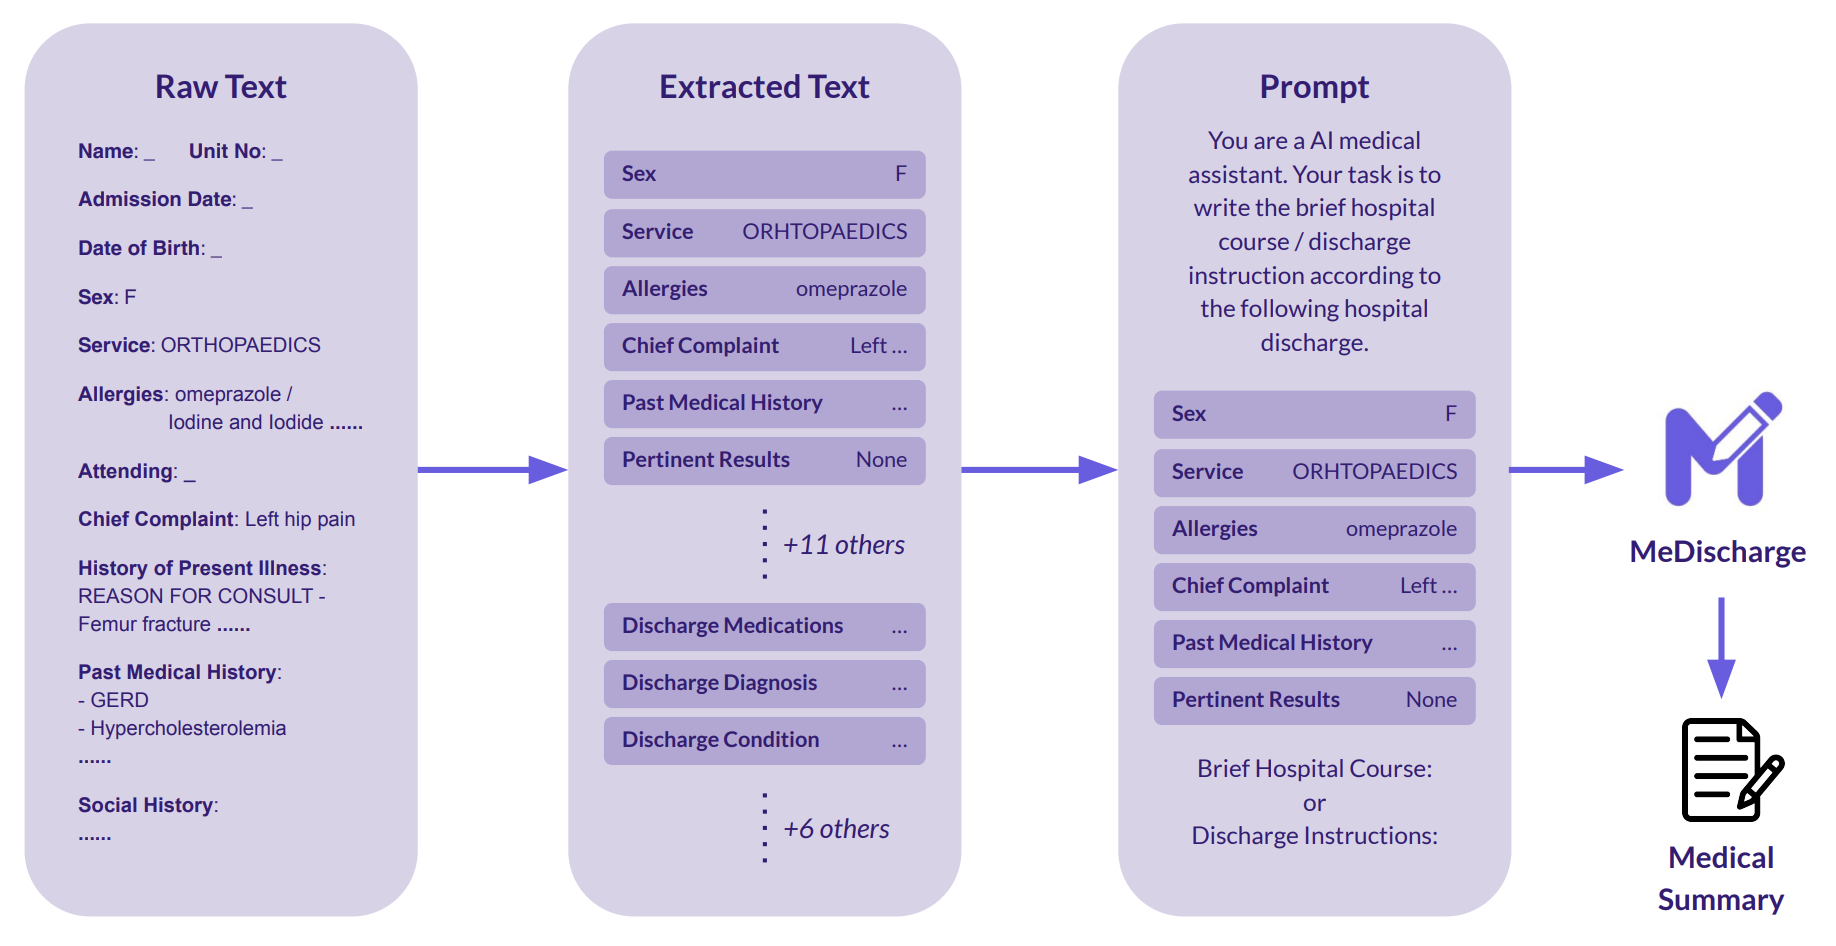
Haotian Wu, Paul Boulenger, Antonin Faure, Berta Céspedes, Farouk Boukil, Nastasia Morel, Zeming Chen, Antoine Bosselut ACL 2024 Workshop on Biomedical Natural Language Processing [Paper] [Code] We present MEDISCHARGE, a Meditron-7B-based system for generating Brief Hospital Course and Discharge Instruction summaries from clinical electronic health records. The system extends the model's context window from 2K to 6K tokens and dynamically selects the most informative record sections when inputs remain too long. MEDISCHARGE improves the shared-task baseline by 183%, achieves a 0.444 ROUGE-1 score, and places second in the competition, demonstrating that domain-specific LLMs and importance-aware information selection can produce accurate discharge documentation efficiently. |
|
[2022.9 - 2026.3] M.S. in Digital Humanities Engineering, EPFL, Switzerland [2018.9 - 2022.6] B.S. in Mathematical Economics and Finance, Xi'an Jiaotong University, China |
|
[2024.8 - 2025.4] NLP Algorithm Researcher, miHoYo, Beijing, China [2024.1 - 2024.8] LLM Infrastructure Developer, ICRC, Geneva, Switzerland |
|
Conferences: ICLR'27 |
|
When I'm not working, I enjoy skiing ⛷️, hiking 🥾, cycling 🚴, and cooking 🍳. I also enjoy playing FPS games!! |
|
I borrowed this website layout from here! |